Adapt CSV for Agile by applying risk-based continuous validation, not by forcing sprints through waterfall gates. Prioritize testing with a risk matrix, automate evidence capture through CI/CD, and keep a live traceability chain from user story to signed test result. Do that, and every sprint closes audit-ready instead of triggering a documentation scramble before the next inspection. The rest of this playbook shows exactly how.
TL;DR:
>
- Risk-based testing prioritizes high-impact, high-likelihood requirements, reducing validation effort on low-risk changes and aligning with GAMP 5 risk categorization.
- Automation pipelines must produce immutable, signed, and traceable evidence, linking tests directly to risk items to satisfy audit requirements in regulated environments.
- Live traceability of requirements, tests, and evidence, along with lighter documentation like auto-generated notes and signed summaries, enables continuous validation within sprints.
- Embedding validation into existing Scrum ceremonies, especially planning and review, ensures timely evidence collection and keeps validation close to daily development workflows.
- Automation platforms can cut validation documentation time by over 70 percent, capturing evidence at work execution and automatically checking compliance principles like ALCOA+.
Table of Contents
- Why Traditional CSV and Agile Are Often at Odds
- Mapping GAMP 5 and Key Regulations to Agile Validation
- Risk-Based Testing: How to Prioritize and Monitor Inside Sprints
- What an Audit-Ready CI/CD Pipeline Looks Like in Agile
- Traceability, Lightweight Documentation, and Change Control That Scale
- A Sprint-Level Playbook You Can Apply This Sprint
- How Automation Platforms Accelerate CSV-to-CSA Adoption
- How CSV Differs from CSA and When to Prefer CSA
- Integrating CSV Into Agile Ceremonies
- The Role of Cross-Functional Teams in Agile CSV
- Common Challenges in Applying CSV to Agile, and What Actually Fixes Them
- Where Agile CSV Implementations Have Worked
- Tools and Technologies Supporting CSV in Agile Workflows
- Matt's Perspective: Pragmatic Adoption and What Actually Blocks It
- Next Steps: How Qualitum Can Help
- Sources
- FAQ
Why Traditional CSV and Agile Are Often at Odds
Classic computerized system validation was built for a world of fixed scope and sequential gates: requirements frozen, then design, then testing, then a validation summary report signed off before go-live. Agile teams ship in one to four week cycles, with scope evolving sprint over sprint. Force the old model onto that cadence, and validation becomes a bottleneck that either slows every release or gets done retroactively, after code is already in production.
Retroactive documentation is where most regulated Agile programs get into real trouble. Teams write code, deploy to a test environment, and only assemble the validation package weeks later when someone remembers an audit is coming. That reconstruction work is unreliable by nature. Testers try to recall why a decision was made, screenshots get backdated, and signatures land on documents that describe intent rather than what was actually observed.
The risk compounds in three specific ways:
- Evidence decay — the further testing evidence is captured from the moment of execution, the more likely it is incomplete or inaccurate.
- Release drag — validation queues stack up behind development, so shipped features wait on paperwork instead of the reverse.
- Audit exposure — inspectors increasingly ask for contemporaneous records, and a validation pack assembled after the fact rarely holds up to that scrutiny.
The FDA's Computer Software Assurance (CSA) initiative offers a way out, not as a replacement for CSV but as a complementary mindset. CSA pushes teams toward risk-based, assurance-focused testing that happens continuously, rather than a document-heavy exercise performed once at the end. It does not remove the obligation to validate; it changes where the effort goes, concentrating rigor on high-risk functionality and letting automation carry the routine assurance load. That shift is exactly what makes CSV compatible with sprint-based delivery instead of constantly working against it.
Mapping GAMP 5 and Key Regulations to Agile Validation
GAMP 5's second edition is built around a simple premise: validation effort should be proportionate to risk, not uniform across every system regardless of complexity. That principle, laid out in ISPE's GAMP 5 guidance, is what makes Agile alignment possible in the first place. GAMP 5 categorizes software by complexity and configurability, and lower-risk categories warrant lighter validation footprints. Applied inside a sprint, that means a configuration change to an off-the-shelf reporting field does not need the same evidentiary weight as a custom algorithm calculating a critical quality attribute.
Two regulations tend to anchor most conversations about what "audit-ready" actually requires:
- 21 CFR Part 11 governs electronic records and signatures in FDA-regulated environments, with expectations around audit trails, record integrity, and access control.
- EU Annex 11 covers computerized systems under EU GMP, with similar emphasis on data integrity, risk management, and change control throughout the system lifecycle.
Both frameworks reward continuous documentation over batch reconstruction. According to the BrowserStack guide on risk-based testing in Agile, continuous evidence capture aligns naturally with Part 11 and Annex 11 expectations because records are generated at the moment of the event rather than assembled afterward from memory and screenshots.
Pro Tip: Build your GAMP 5 category assessment into sprint zero, not as a one-time project artifact. Revisit the category whenever a feature's risk profile changes, since a configuration item can graduate into higher-risk territory as its use expands.
One caveat matters more than any framework detail: regulatory expectations vary by jurisdiction, by product type, and by the specific inspection history of a facility. GAMP 5 and the citations above describe widely accepted risk-based principles, but they are not a substitute for consulting your own regulatory affairs function and the primary text of the regulations that govern your market before finalizing a validation strategy.
Risk-Based Testing: How to Prioritize and Monitor Inside Sprints
Risk-based testing (RBT) is the mechanism that actually makes CSV work inside sprint boundaries. Instead of testing everything to the same depth, RBT scores each requirement or user story by likelihood of failure and impact of that failure, then routes testing effort accordingly. The BrowserStack guide describes this as the primary bridge between Agile velocity and compliance rigor, built around a likelihood times impact matrix and ongoing risk burndown tracking.
Building the risk matrix starts with a simple calculation: Risk Priority Number (RPN) equals the product of Likelihood and Impact. Score each on a scale of 1 to 5, multiply, and you get a number that tells you where testing effort should concentrate first.
- Identify the risk — pull candidate items from the sprint backlog, focusing on anything touching patient safety, data integrity, or regulated calculations.
- Score likelihood — rate how probable a defect is, based on code complexity, prior defect history, and how novel the functionality is.
- Score impact — rate the consequence if that defect reaches production, from cosmetic to safety-critical.
- Calculate RPN — multiply the two scores to rank items against each other.
- Assign test depth — high RPN items get full functional, boundary, and negative testing; low RPN items get a lighter smoke check.
- Reassess mid-sprint — scope changes, so a story that looked low-risk on day one can shift once a dependency reveals itself.
Risk workshops work best as a short, cross-functional session near the start of sprint planning. Development, QA, product owners, and a validation representative each bring a different lens: developers know where the code is fragile, QA knows where regressions have historically clustered, product owners know which features carry business or patient impact, and validation knows what regulators will actually ask about later.
| Risk Priority Level | Testing Depth | Typical Evidence |
|---|---|---|
| Critical risk | Full functional, boundary, negative, and regression testing | Signed test protocol, screenshots, automated test logs |
| Moderate risk | Functional testing plus targeted edge cases | Automated test results, exception log review |
| Low risk | Smoke test or configuration check | Automated pass/fail record |
Three artifacts keep RBT visible and defensible over time: a risk register that logs every scored item and its disposition, a test-case priority grid that maps RPN scores to specific test cases, and a risk burndown chart that tracks how many high-priority risks remain open as the sprint progresses. Practitioner analysis in the Global Journals report on risk-based testing found that teams combining these artifacts with automated test selection reduced critical defects while cutting overall test volume, because effort stopped being spread evenly across items that did not deserve equal attention.
What an Audit-Ready CI/CD Pipeline Looks Like in Agile
Automation is what turns risk-based testing from a good idea into evidence a regulator will accept. A pipeline built for regulated Agile work needs to produce the same reproducible record every time it runs, not just a pass or fail notification.
Four pipeline characteristics separate an audit-ready setup from a merely fast one:
- Immutable builds — every release artifact is versioned and locked, so nobody can quietly patch a build after it passed testing.
- Signed test runs — automated test results carry a tamper-evident record of who or what executed them and when.
- Environment snapshots — the configuration state of the test environment is captured alongside results, since a passing test in a drifted environment proves very little.
- Artifact retention — build outputs, logs, and test evidence are retained long enough to satisfy retention requirements, not purged at the next pipeline run.
The Pharma GMP analysis of Agile and GAMP 5 alignment identifies these four elements as foundational to defensible evidence in regulated pipelines, arguing that automation without them just produces faster, unverifiable results.
Test-driven development (TDD) and behavior-driven development (BDD) reinforce this by writing the validation criteria before the code exists. A BDD scenario written in plain language, "given a batch record with an out-of-range value, the system rejects the entry," doubles as both a development spec and a validation test case. Automated regression suites then re-run that scenario on every build, generating continuous evidence that the control still works rather than relying on a one-time test executed months earlier.
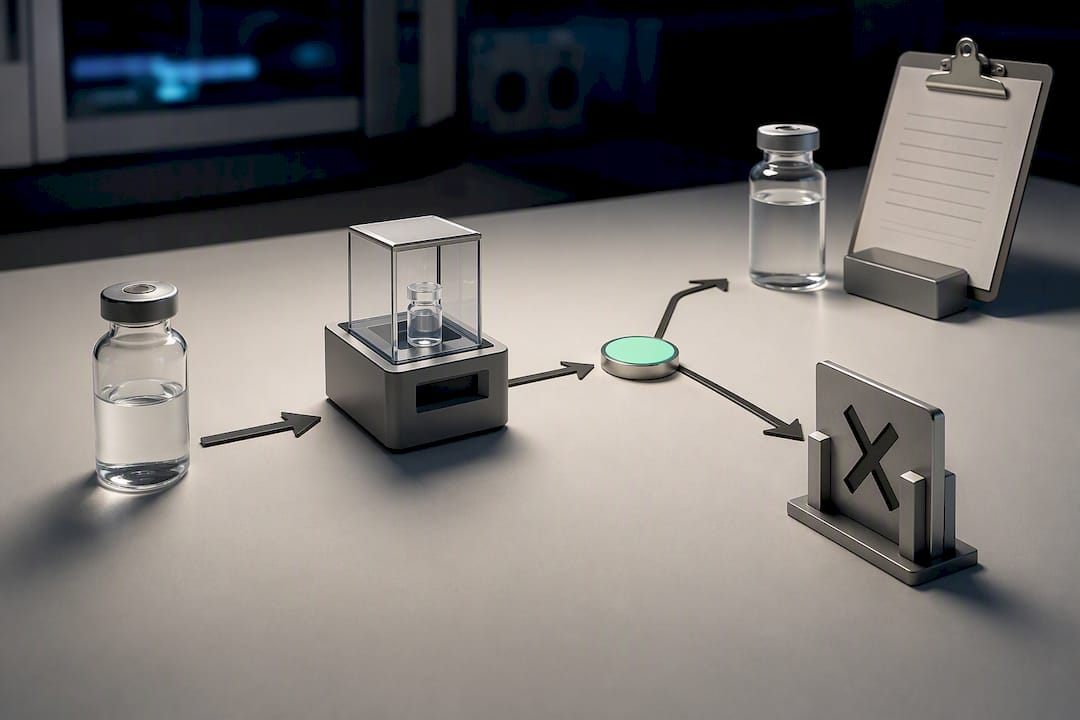
The last piece is integration. Evidence needs to flow out of the pipeline and into wherever your quality management system expects it, whether that's an artifact store, a test orchestration platform, or a direct export into a document control system. A pipeline that produces excellent evidence nobody can retrieve during an inspection is not meaningfully better than no automation at all.
Pro Tip: Tag every automated test run with the risk register item it satisfies. When an auditor asks how you know a high-risk function was tested this sprint, you want a direct link, not a search through commit history.
Traceability, Lightweight Documentation, and Change Control That Scale
Requirements traceability is where a lot of Agile CSV efforts fall apart, usually because teams try to maintain a traditional traceability matrix as a static spreadsheet updated once at the end of a release. That approach cannot keep pace with weekly sprints. Live traceability instead links each user story to its requirement, its automated test, and the evidence that test produced, updating automatically as work moves through the pipeline rather than through manual re-entry.
The Pharma GMP guidance on Agile and GAMP 5 recommends documenting how iterative cycles map to lifecycle phases explicitly, rather than assuming a reviewer will infer the connection. That means your validation strategy document should state, in plain terms, which sprint activities correspond to which GAMP 5 lifecycle stage.
Documentation itself needs to get lighter without getting less defensible. A few patterns hold up well under audit:
- Auto-generated release notes that pull directly from completed story tickets, rather than a manually compiled summary written days later.
- Signed test summaries produced at the point of execution, carrying a timestamp and executor identity rather than a batch signature applied afterward.
- Story-to-requirement links maintained inside the same tool the team already uses for sprint tracking, so there is no separate system to keep synchronized.
Change control needs its own adaptation for sprint cadence. A feature toggle that ships dark and gets enabled later is a different risk profile than a hotfix pushed to address a production defect, and both differ again from a planned enhancement scheduled two sprints out. Each pattern needs a proportionate control:
- Feature toggles get a lightweight review at the point of activation, not just at code merge, since the risk exposure changes the moment the toggle flips on.
- Hotfixes get an expedited but still documented review, capturing what changed and why, even when the full sprint ceremony gets skipped for speed.
- Planned enhancements follow the standard sprint risk triage and testing depth assigned during planning.
Skipping change control for hotfixes is one of the most common gaps auditors find, precisely because "we needed it fast" is not a substitute for a record of what changed.
A Sprint-Level Playbook You Can Apply This Sprint
Turning all of this into practice comes down to embedding validation checkpoints into ceremonies your team already runs, rather than adding a parallel process nobody has time for.
- Sprint planning: risk triage. Score new backlog items using the RPN method, flag anything touching data integrity or patient safety, and write acceptance criteria that explicitly state what evidence will be captured.
- Definition of Done, updated. Add evidence capture and trace-link creation as a formal Definition of Done criterion. A story is not done if its test evidence is not linked to its requirement.
- Daily stand-ups: risk reassessment. Spend thirty seconds flagging any scope change that might shift a risk score, since a story that grew in complexity mid-sprint may need a testing depth upgrade.
- Mid-sprint: automated checkpoints. Run smoke tests against every merge, not just at the end of the sprint, so regressions surface while there is still time to fix them inside the current cycle.
- Sprint review: demonstrate evidence, not just features. Show the trace links and signed test results alongside the working software, so validation visibility becomes a normal part of the review rather than a separate audit exercise.
- Retrospective: risk register review. Ask what got missed, what took longer than expected to test, and whether the risk scoring model needs recalibration for the next cycle.
- Sprint close: consolidate the release artifact. Package the trace matrix, signed evidence, and updated risk register into a release-ready bundle before the sprint officially ends, not after the next one starts.
Following this sequence means the validation package for a release is never more than one sprint's worth of consolidation away from complete, because every ceremony already contributed a piece of it.
How Automation Platforms Accelerate CSV-to-CSA Adoption
Manual documentation is where most Agile CSV programs lose the time they gained from moving faster in development. Someone still has to write the protocol, capture the screenshot, format the summary, and chase a signature, and that work rarely shrinks just because the code shipped quickly.
Automation platforms built specifically for this problem report over 70% time savings in authoring validation documents, largely by capturing evidence at the moment an event happens rather than reconstructing it afterward. A multi-agent system generates validation artifacts, URS through PQ, as work happens, with every record checked against ALCOA+ principles (attributable, legible, contemporaneous, original, accurate, plus the newer additions of complete, consistent, enduring, and available) at both write-time and review-time.
That double check matters because most audit findings trace back to gaps that manual processes create by nature: a missing signature, a screenshot with no timestamp, a test result that never got linked back to its requirement. Automated evidence capture removes the human step where those gaps typically open up.
For teams evaluating where to start, three pilot use cases tend to prove value fastest:
- Automating protocol authoring for a single high-traffic system to measure the time savings directly.
- Running live traceability automation on one active project to see trace links update in real time.
- Using automated evidence capture to prepare for an upcoming internal audit as a low-stakes proof point before scaling further.
How CSV Differs from CSA and When to Prefer CSA
CSV is the validation process itself: the documented activity of proving a computerized system does what it claims to do, consistently and reliably. CSA is a philosophy for how to execute that process, emphasizing risk-based, assurance-focused activities over document-heavy, one-size-fits-all testing. The two are not competing frameworks. CSA describes how to do CSV more efficiently, not a replacement for the underlying validation obligation.
The practical distinction shows up in where effort goes. A traditional CSV approach might require the same depth of scripted testing for a low-risk configuration change as for a high-risk custom calculation, because the process treats every change uniformly. A CSA-aligned approach asks first what could go wrong and how severe that would be, then scales testing rigor to match, often substituting unscripted exploratory testing and vendor-supplied evidence for redundant scripted test scripts on lower-risk items.
CSA tends to make the most sense in a few recurring situations:
- Commercial off-the-shelf systems with vendor-documented testing already covering core functionality, where duplicating that testing internally adds little assurance.
- Configuration-only changes within a previously validated system, where the underlying code has not changed.
- High-frequency, low-risk releases, common in Agile environments, where full scripted revalidation on every sprint would create a backlog with no proportional safety benefit.
A traditional, more document-heavy CSV approach still fits situations involving custom-built, high-risk functionality, novel algorithms affecting product quality, or systems with a history of significant defects. The choice is not either-or across an entire organization. It is a per-system, per-change judgment, made using the same risk scoring already built into your GAMP 5 categorization and RBT process.
Integrating CSV Into Agile Ceremonies
Validation activities stick when they live inside ceremonies the team already runs, rather than existing as a separate meeting nobody wants to attend. Sprint planning is where risk triage belongs, scoring new backlog items and writing acceptance criteria that name the specific evidence a story will need before it counts as done.
Daily stand-ups carry a much smaller validation footprint, but not a zero one. A thirty-second flag on any story whose scope changed is often enough to catch a risk score that needs revisiting before the sprint ends.
Sprint reviews are the most underused ceremony for validation visibility. Most teams demo working software and stop there. Adding a brief look at the trace links and signed test evidence behind that software turns the review into a natural checkpoint for stakeholders, including quality representatives, without adding a separate audit meeting to the calendar.
Retrospectives close the loop by asking what validation friction actually happened. Did a risk score turn out wrong? Did evidence capture slow the team down more than expected? These questions belong in the same retrospective format the team already uses for process improvement, not in a separate quality retrospective that gets deprioritized when the sprint runs long.
The pattern across all four ceremonies is the same: validation is not bolted onto Agile process, it rides inside process the team already values enough to protect.
The Role of Cross-Functional Teams in Agile CSV
Risk-based validation only works when the people who understand risk from different angles are actually in the room together, not reviewing each other's work in sequence after the fact. A typical risk workshop needs four perspectives at minimum: a developer who knows where the code is fragile, a QA engineer who knows where regressions have clustered historically, a product owner who understands business and patient impact, and a validation or quality representative who knows what a regulator will ask about later.
Leaving validation out of sprint planning is one of the most common structural mistakes regulated Agile teams make. When validation only shows up at the end of a release cycle, it inherits risk decisions it had no voice in shaping, and pushback at that stage reads as an obstacle rather than a contribution.
Cross-functional ownership also changes who is accountable for evidence. In a siloed model, QA tests and validation documents, with a handoff in between that introduces delay and interpretation error. In an integrated model, the person writing the automated test also tags it against the risk register item it satisfies, collapsing that handoff into a single step. That single change removes one of the most common sources of missing or mismatched trace links.
Common Challenges in Applying CSV to Agile, and What Actually Fixes Them
Three challenges show up in nearly every regulated Agile transformation, and none of them are solved by better documentation templates.
Culture friction tops the list. Quality teams trained on waterfall validation often see sprint speed as a threat to rigor, while development teams see quality gates as a threat to velocity. The fix is not a mandate from either side. It is a shared risk model, built in workshops rather than handed down, so both groups are scoring the same risks using the same criteria instead of negotiating from opposite assumptions.
Tooling silos come next. Sprint tracking lives in one system, test execution in another, and document control in a third, with manual re-entry connecting them. That gap is exactly where trace links break and evidence goes missing. Reducing the number of manual handoffs between systems matters more than picking any specific tool.
Skill gaps round out the list. QA professionals trained in scripted validation testing may not have exploratory or risk-scoring experience, and developers writing BDD scenarios may not know what a regulator will expect to see in the resulting evidence. Pairing validation staff directly with development pods during a pilot sprint, rather than training everyone separately beforehand, tends to close that gap faster than any workshop series.
Where Agile CSV Implementations Have Worked
Successful Agile CSV programs share a pattern regardless of company size or product type: they start narrow, prove the model on one team, then expand once the evidence holds up under real scrutiny rather than assumption.
A common starting point is a single product team piloting risk-based testing on one release train while the rest of the organization continues with existing validation practices. The TestRail analysis of Agile risk-based testing describes teams reviewing past sprint backlogs and defect data by risk area as the persuasive step that gets skeptical stakeholders on board, since the comparison between testing effort and actual defect density makes the case better than any policy argument.
The teams that sustain the change past the pilot tend to do one thing consistently: they invite quality and audit stakeholders to observe evidence flowing through the pipeline in real time during the pilot, rather than waiting to present a finished validation package after the fact. Watching a signed test result get generated automatically, tagged to its trace link, builds a kind of trust that a slide deck describing the same process cannot.
The pattern that fails, just as consistently, is trying to convert an entire organization at once. Programs that attempt an all-at-once cutover from document-heavy CSV to continuous validation tend to stall, because too many teams are learning a new risk model, a new tooling chain, and a new ceremony structure simultaneously, with no working example to point to when something goes wrong.
Tools and Technologies Supporting CSV in Agile Workflows
No single tool covers the full Agile CSV workflow, and treating any one platform as sufficient is usually where gaps reappear. A functioning stack tends to combine several categories of tooling working together.
Sprint and backlog management platforms hold the risk-scored user stories and acceptance criteria, serving as the anchor point that everything else links back to. Test automation and orchestration tools execute the scripted and exploratory tests defined by the risk matrix, generating the signed results that feed into evidence. CI/CD pipeline tools produce the immutable builds and environment snapshots that make those test results reproducible rather than one-off claims. Artifact and document stores retain builds, logs, and evidence long enough to satisfy retention requirements, ideally with version control that prevents silent edits after the fact.
Sitting across all of these, purpose-built validation automation platforms are increasingly filling the gap that manual coordination used to leave open: connecting the risk register, the test evidence, and the traceability matrix into one continuously updated record instead of four disconnected systems that someone has to reconcile by hand at release time. That connective layer is where most of the manual authoring time in traditional CSV actually goes, and where automation tends to deliver the clearest return.
Matt's Perspective: Pragmatic Adoption and What Actually Blocks It
The biggest blocker to Agile CSV adoption is rarely technical. It is culture, specifically the assumption that speed and rigor are opposing forces. Quality teams trained on waterfall validation often resist sprint cadence not because the risk model is wrong, but because nobody built trust in the new evidence before asking them to rely on it.
The fix that actually works is smaller than most transformation plans suggest: pick one pilot sprint, document it completely, and invite an auditor or internal quality reviewer to watch the evidence get generated in real time. Trust builds faster from watching a signed test result appear automatically than from reading a policy document describing how it will work.
Tooling silos and skill gaps matter too, but they are solvable with time and budget. Culture resistance is not, unless someone earns credibility early with a concrete, observable win.
Three metrics tell you whether the shift is working: validation cycle time from story to signed evidence, evidence completeness rate at sprint close, and release frequency compared to your pre-adoption baseline. If cycle time is not dropping and completeness is not climbing, the risk model needs recalibration before you scale it further.
— Matt
Next Steps: How Qualitum Can Help
Qualitum gives validation-heavy pharmaceutical, biotech, and medical device teams a way to keep sprint speed without inheriting the manual documentation burden that usually comes with it. If your team is spending more time authoring protocols and chasing signatures than actually testing, that is the specific gap the platform's Validate·AI capability targets, generating URS through PQ evidence continuously and checking every record against ALCOA+ at write-time and review-time.
The path in is deliberately low-commitment. Start with a free validation gap report to see where your current CSV process is losing time to manual authoring or fragmented evidence. From there, most teams book a working session to walk through a pilot on one system or one release train before any broader rollout conversation happens. Nothing about the process assumes an enterprise commitment on day one. It assumes you want to see the evidence flow before you decide anything else, and that pilot is exactly where the case for scaling gets made or does not.
Sources
Regulatory text changes slower than practice, so the primary sources below are worth bookmarking alongside the practitioner guides that informed this playbook.
- Risk-Based Testing in Agile (BrowserStack guide)
- Agile risk-based testing (TestRail blog)
- Fail fast, fix faster: Risk-based testing for agile product teams (Global Journals)
- What you need to know about GAMP 5 (ISPE)
FAQ
What does CSV stand for in this context?
CSV stands for Computerized System Validation, the documented process of proving a computerized system consistently performs as intended in a regulated environment.
What is GxP, and how does it relate to CSV?
GxP is a collective term for the quality standards, good practice guidelines, that govern regulated industries such as pharmaceuticals and medical devices, and CSV is the validation process required to demonstrate that computerized systems supporting GxP processes work reliably.
How does CSV differ from CSA?
CSV is the underlying validation obligation, while CSA (Computer Software Assurance) is a risk-based philosophy for executing that obligation more efficiently, favoring assurance activities scaled to actual risk over uniform, document-heavy testing on every change.
Can CSV really work inside two-week sprints?
Yes, when validation activities are embedded into existing ceremonies, risk triage in planning, evidence capture as part of Definition of Done, and consolidation at sprint close, rather than treated as a separate gate at the end of a release.
How can automation reduce CSV documentation time?
Platforms like Qualitum capture evidence at the moment work happens and apply ALCOA+ checks automatically, which is how vendor reporting shows over 70% time savings in validation document authoring compared to manual processes.
Recommended
- CSV Automation for Validation Teams: A CSA-Aligned Roadmap
- CSV to CSA: The FDA Transition Playbook for QA Teams
- Part 11 Compliance: Inspection-Ready Checklist for QA Teams
- Audit Readiness Checklist for Validation and QA Leaders
FAQ
What does CSV stand for in this context?
CSV stands for Computerized System Validation, the documented process of proving a computerized system consistently performs as intended in a regulated environment.
What is GxP, and how does it relate to CSV?
GxP is a collective term for the quality standards, good practice guidelines, that govern regulated industries such as pharmaceuticals and medical devices, and CSV is the validation process required to demonstrate that computerized systems supporting GxP processes work reliably.
How does CSV differ from CSA?
CSV is the underlying validation obligation, while CSA (Computer Software Assurance) is a risk-based philosophy for executing that obligation more efficiently, favoring assurance activities scaled to actual risk over uniform, document-heavy testing on every change.
Can CSV really work inside two-week sprints?
Yes, when validation activities are embedded into existing ceremonies, risk triage in planning, evidence capture as part of Definition of Done, and consolidation at sprint close, rather than treated as a separate gate at the end of a release.
How can automation reduce CSV documentation time?
Platforms like Qualitum capture evidence at the moment work happens and apply ALCOA+ checks automatically, which is how vendor reporting shows over 70% time savings in validation document authoring compared to manual processes.